





AI & Innovation
RAG vs. Fine-Tuning: How to Choose the Right LLM Architecture for Your Enterprise
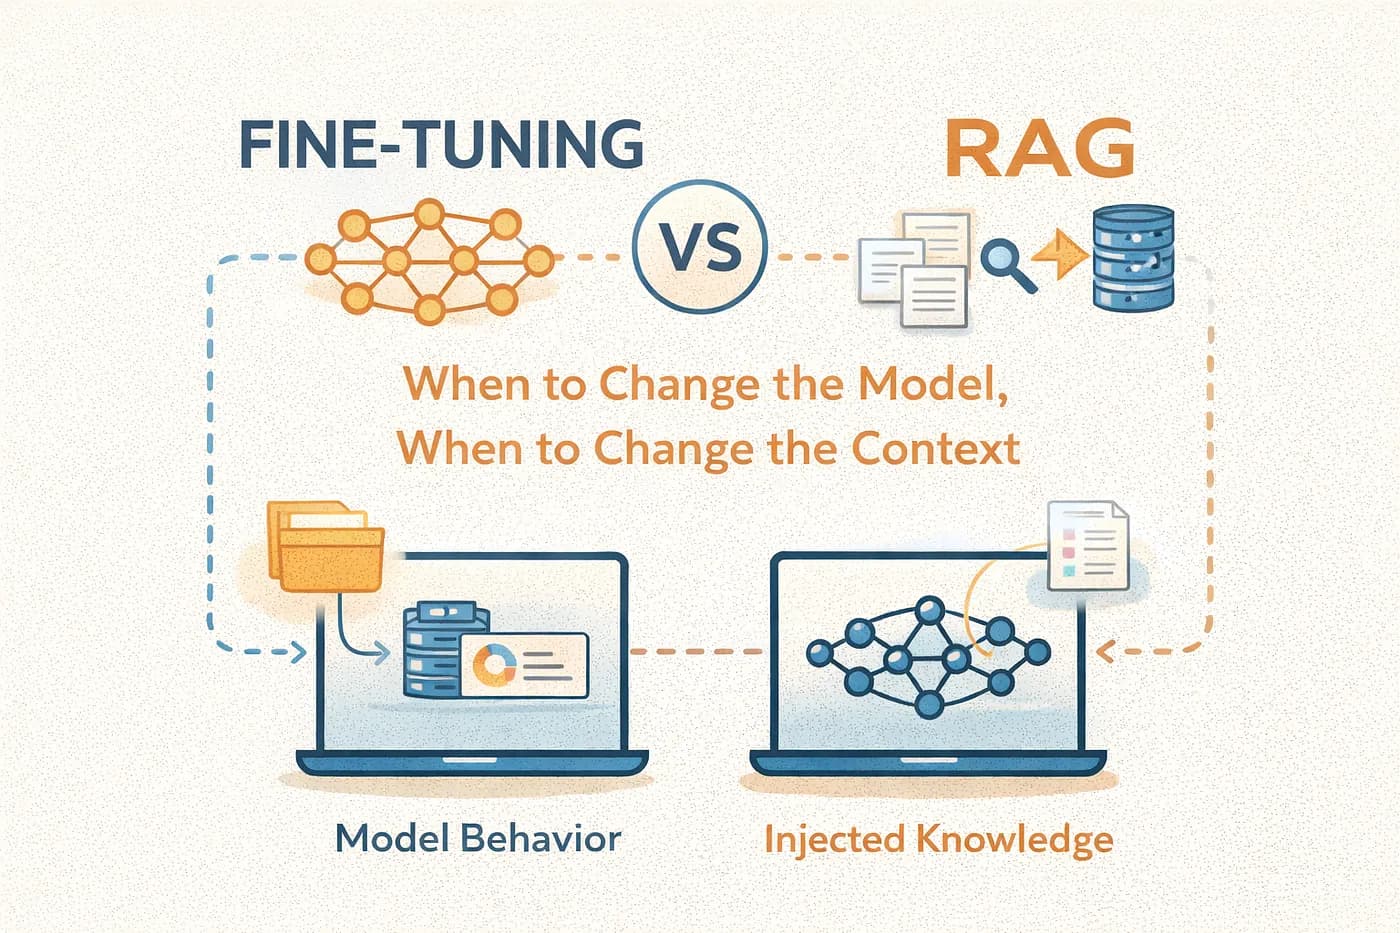
As enterprises rush to integrate Generative AI into their core operations, decision-makers face a critical architectural fork in the road: Retrieval-Augmented Generation (RAG) or Fine-Tuning. While both pathways promise to customize Large Language Models (LLMs) with proprietary business data, they serve fundamentally different technical needs, carry distinct cost profiles, and solve separate classes of problems. This guide breaks down the mechanics, trade-offs, and decision matrices to help your engineering team choose the optimal path for your enterprise workloads.